

QUESTION NO: 1
Which of the following can be used to compare the relative prevalence of specific values in a single categorical variable between two datasets or time periods?
Which of the following can be used to compare the relative prevalence of specific values in a single categorical variable between two datasets or time periods?
Correct Answer: D
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 2
A machine learning engineer is migrating a machine learning pipeline to use Data bricks Machine Learning. The pipeline needs to automatically refresh its model each time it runs.
They are using the following code block as part of their solution:
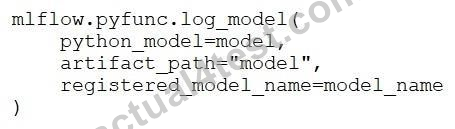
Assuming that this is the first time that the model is being run, which statement describes the impact of the registered_model_name=model_name parameter?
A machine learning engineer is migrating a machine learning pipeline to use Data bricks Machine Learning. The pipeline needs to automatically refresh its model each time it runs.
They are using the following code block as part of their solution:
Assuming that this is the first time that the model is being run, which statement describes the impact of the registered_model_name=model_name parameter?
Correct Answer: D
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 3
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a run with run ID run_id for the experiment with experiment ID exp_id, the data scientist wants to programmatically return the logged metrics for run_id. They have an active MLflow Client client and an active Spark session spark. Which lines of code can be used to return the logged metrics for run_id?
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a run with run ID run_id for the experiment with experiment ID exp_id, the data scientist wants to programmatically return the logged metrics for run_id. They have an active MLflow Client client and an active Spark session spark. Which lines of code can be used to return the logged metrics for run_id?
Correct Answer: C
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 4
A data scientist wants to log outlier feature data from a CSV file at path outlier_path with an MLflow run for model model. Which code block will accomplish this task inside of an existing MLflow run block?
A data scientist wants to log outlier feature data from a CSV file at path outlier_path with an MLflow run for model model. Which code block will accomplish this task inside of an existing MLflow run block?
Correct Answer: A
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 5
A Machine Learning Engineer needs to build a credit risk model using Databricks. Due to strict data governance, production data cannot be accessed from development or staging environments. To manage MLOps, the engineer uses a "deploy code" strategy with separate development, staging, and production environments mapped to different catalogs in Unity Catalog. The CI/CD pipeline automates environment transitions. What is the primary architectural component promoted from staging to production to generate the final, production-ready model in this scenario?
A Machine Learning Engineer needs to build a credit risk model using Databricks. Due to strict data governance, production data cannot be accessed from development or staging environments. To manage MLOps, the engineer uses a "deploy code" strategy with separate development, staging, and production environments mapped to different catalogs in Unity Catalog. The CI/CD pipeline automates environment transitions. What is the primary architectural component promoted from staging to production to generate the final, production-ready model in this scenario?
Correct Answer: D
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 6
A Data Scientist needs to perform inference on a continuously updated Delta table called sales_data using an MLflow-registered Spark ML pipeline model (catalog.prod.sales_forecaster).
Predictions must be written to a Delta table forecast_results, which must be updated with low latency leveraging a cluster with three executors. They want to maximize the efficient use of their cluster when doing this. Which approach will suit their needs?
A Data Scientist needs to perform inference on a continuously updated Delta table called sales_data using an MLflow-registered Spark ML pipeline model (catalog.prod.sales_forecaster).
Predictions must be written to a Delta table forecast_results, which must be updated with low latency leveraging a cluster with three executors. They want to maximize the efficient use of their cluster when doing this. Which approach will suit their needs?
Correct Answer: A
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 7
A machine learning engineer is monitoring label values for a production machine learning classification model. The engineer believes that the relative prevalence of the classes is becoming changing in more recent data. Which tool can the machine learning engineer use to assess their theory?
A machine learning engineer is monitoring label values for a production machine learning classification model. The engineer believes that the relative prevalence of the classes is becoming changing in more recent data. Which tool can the machine learning engineer use to assess their theory?
Correct Answer: D
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).
QUESTION NO: 8
Which Spark ML class supports automated hyperparameter tuning?
Which Spark ML class supports automated hyperparameter tuning?
Correct Answer: A
Vote an answer
Explanation: Only visible for Actual4test members. You can sign-up / login (it's free).